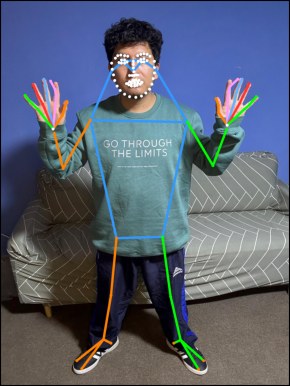
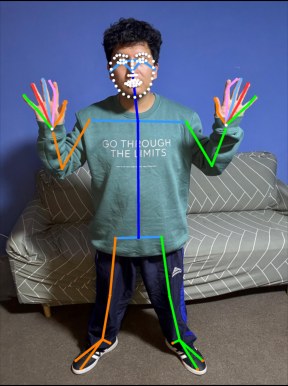
TL;DR Every pose estimator speaks its own dialect. WholeBodyPose puts RTMPose (RTMW), ViTPose+ and MediaPipe behind one interface that always returns the 133 COCO-WholeBody keypoints (body, feet, face, both hands), plus the video pipeline, temporal filtering (NLMS) and visualization needed to turn raw sign language videos into training-ready pose sequences. We release the pose sequences of 13 ISLR subsets built with it.
Abstract
Sign language recognition systems require high-quality, temporally consistent pose estimation data for effective training. However, existing approaches suffer from inconsistent output formats across different pose estimation models, inadequate temporal filtering, and a lack of standardized preprocessing pipelines. We present WholeBodyPose, an end-to-end framework that unifies multiple state-of-the-art pose estimation models (MediaPipe, RTMPose, ViTPose) under a standardized COCO-133 format. Our framework addresses the critical gaps identified in recent work, providing researchers with a consistent interface to generate high-quality training data.
We provide a modular architecture that supports the easy integration of new pose estimation models, including preprocessing pipelines from raw video input to training-ready keypoint sequences, quality control mechanisms, and visualization tools. Additionally, our library is optimized for real-time use cases, enabling seamless integration into live inference pipelines and interactive sign language systems. This capability makes it suitable not only for research and training, but also for deployment in production-level applications. Our open-source library democratizes access to high-quality pose-based sign language recognition research and establishes a new standard for preprocessing pipelines in this domain.
Keywords: Sign Language Recognition, Pose Estimation, Framework, Keypoint Filtering, Real Time Processing